Derived Variables
Draft - not in a release yet
This page describes a feature that is in development. It is published early so the wording and the screenshots can be reviewed; the behaviour described here ships in the next release.
A derived variable is a column that does not exist in the target table, but is computed when the table is loaded into the EDIT screen. It is read-only, it appears after the physical columns, and it can be filtered on like any other column.
Derived variables are useful when users need to work with a value that is a function of the stored data - a banding, a concatenation, a calculation - without changing the table, the load process, or the ETL.
The values are not stored. They are computed on every read, and nothing derived is written back when a change is submitted or approved.
What it looks like
The table below is shown in the EDIT screen. LINE_VALUE is QTY * PRICE and REGION is derived from STATE; neither exists in the table itself, and both are read-only.
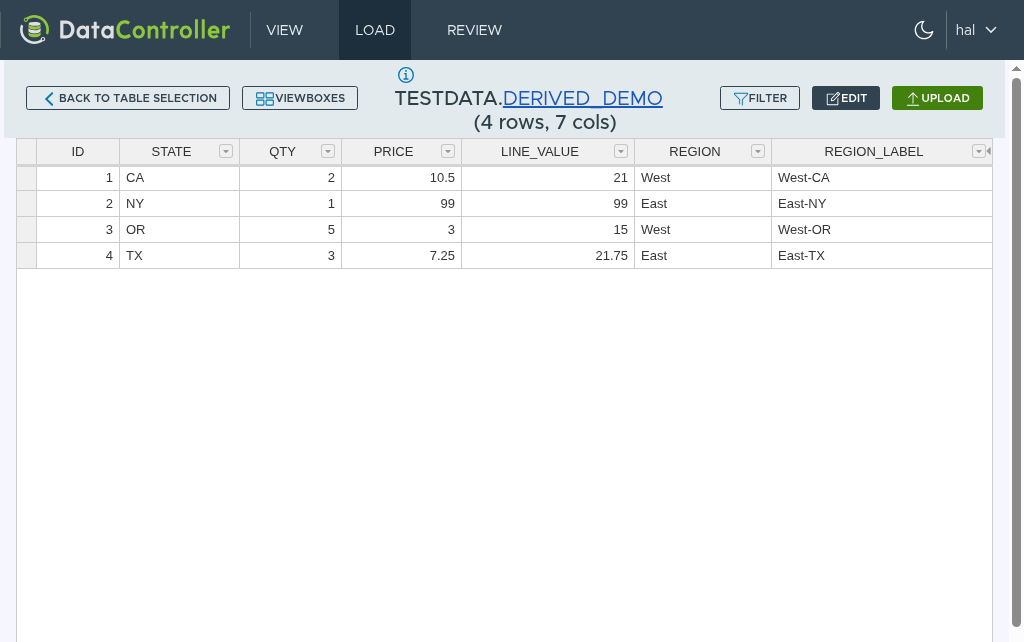
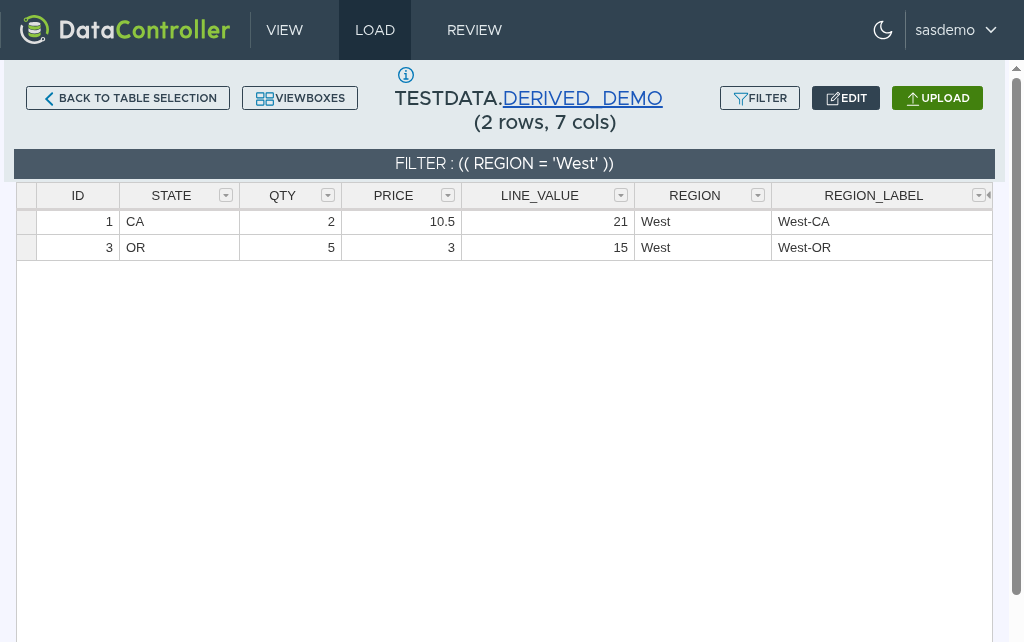
Because the derived columns are created before the filter is applied, they can be filtered like any other column. Here REGION = 'West' selects the two western states, and the filter bar names the derived variable:
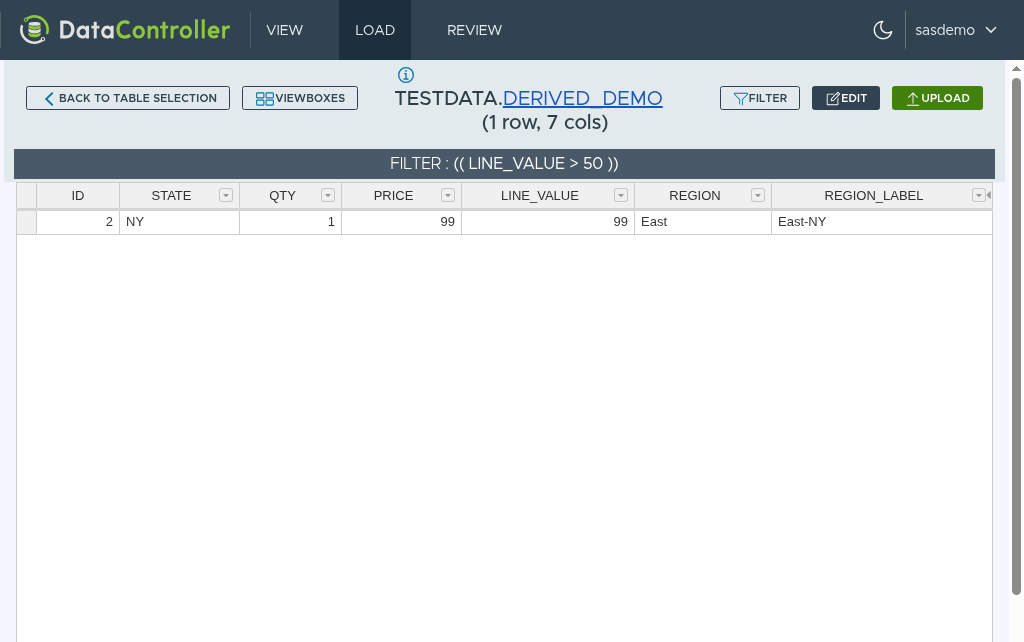
A numeric derived column works the same way - LINE_VALUE > 50 leaves the one row that satisfies it:
How it works
The statements are written into a DATA step view over the target table, and the filter is applied to that view rather than to the table:
data work.vw_derived / view=work.vw_derived;
  set &libds;
  attrib REGION length=$8 label='...' format=$8.;
  REGION = ifc(STATE in ('CA','OR','WA'),'West','East');
run;

data out;
  set work.vw_derived;
  where %inc filtref;;
run;
A WHERE statement applies to the data set named on the SET statement, so in a single step it cannot see a variable created later in the same step. Putting the derived variables on the view means they are on the input to the step that filters, which is what makes them filterable at all.
Configuration
Derived variables are configured per table in the MPE_DERIVED control table, which is itself a Data Controller table - so it is maintained through the EDIT screen with the usual review and approve workflow. The three variables shown above, and nothing else, are the three rows below:
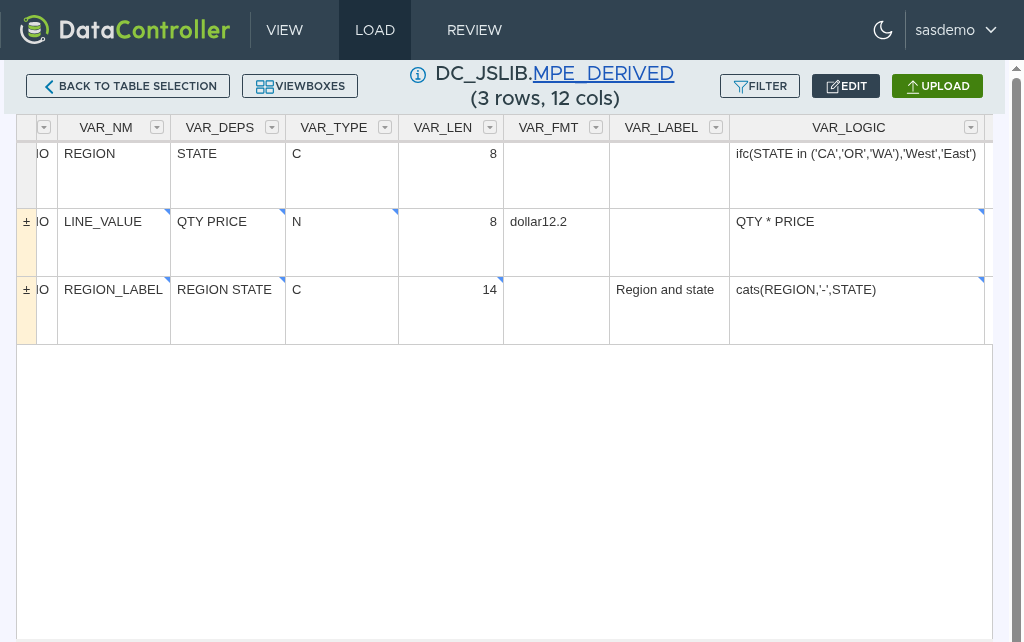
Each row defines one variable:
LIBREF/DSN- the target tableVAR_NM- the name of the new columnVAR_DEPS- every input the expression uses: the physical columns and any derived variables, space separatedVAR_TYPE-Cfor character,Nfor numericVAR_LEN- character length, or numeric length (1-8)VAR_FMT- optional, egDATE9.orDOLLAR12.2VAR_LABEL- optional; when blank the label is<VAR_NM>=<expression>VAR_LOGIC- the SAS expression that produces the valueACTIVE- set to 1 to apply the variable
A simple example, deriving a region from a state:
VAR_NM      REGION
VAR_DEPS    STATE
VAR_TYPE    C
VAR_LEN     8
VAR_FMT     (blank)
VAR_LABEL   (blank)
VAR_LOGIC   ifc(STATE in ('CA','OR','WA'),'West','East')
ACTIVE      1
A second variable can build on it - its dependencies include the physical column and the derived one:
VAR_NM      REGION_LABEL
VAR_DEPS    REGION STATE
VAR_TYPE    C
VAR_LEN     14
VAR_FMT     (blank)
VAR_LABEL   Region and state
VAR_LOGIC   cats(REGION,'-',STATE)
ACTIVE      1
There is no sequence number to maintain. The statements are emitted in dependency order, so REGION is always assigned before REGION_LABEL, however the rows are ordered in the table.
For each row, Data Controller generates the following statements when the table is read:
attrib REGION length=$8 label='REGION=ifc(STATE in (''CA'',''OR'',''WA''),''West'',''East'')' format=$8.;
REGION = ifc(STATE in ('CA','OR','WA'),'West','East');
The label is VAR_LABEL when one is supplied, otherwise the variable name, an equals sign and the expression - REGION=ifc(...) - so the column shows both what it is and where it comes from when labels are switched on. Either way the label is truncated to the maximum label length, on a boundary that cannot split a doubled quote.
The type and length are declared, not inferred, so a value is truncated exactly as you specify. If VAR_FMT is left blank, character variables default to $<length>. and numeric variables to <length>.; a date, time or datetime format makes the column render (and filter) as a date, time or datetime, the same way a stored column does.
Filtering
The derived variable is created before the filter is applied, so it can be used in the filter like any other column - including its list of values. A filter on a derived column is stored and re-applied in the normal way, and the value list for a derived column is built from the table under the rest of the filter, exactly as for a stored column.
Derived columns themselves are an EDIT screen feature: the VIEW screen and the download services do not show them. A saved filter that references a derived column still applies there, and is evaluated the same way.
Rules and limits
- Expressions only.
VAR_LOGICmust be a single SAS expression - no semicolons, macro triggers (%,&) or comments. Conditional logic is available through functions such asifc(),choosec(),cats(),catx(),put(),input()andintnx(). - Dependencies declared.
VAR_DEPSlists every input the expression uses - physical columns and derived variables alike. Statements are generated in dependency order, so no sequence number is maintained, and the declaration is checked in both directions: every reference must be declared, and every declared name must be referenced and must exist. Circular references are rejected. - No collisions.
VAR_NMmust not match an existing column of the target table, or_____DELETE__THIS__RECORD_____. - Read-only. Derived columns cannot be edited in the grid, and any value submitted for them is discarded before the approval package is created.
- Recomputed on every read. The value always reflects the current data and the current definition, and there is no history of previous derived values.
A configuration error - a bad name, an invalid type or length, a name collision, or a reference to a derived variable that is not declared in VAR_DEPS - stops the EDIT screen with a message naming the variable. A syntax error or an unknown column in the expression itself is caught when the view is compiled, and stops the screen with a message naming the table.
Most of these rules are also applied when a row is submitted for approval, through a post edit hook on MPE_DERIVED. A bad name, type, length, format or expression - or a reference to a derived variable that is not declared in VAR_DEPS - is rejected at submit time, while the error can still be corrected, rather than breaking the EDIT screen afterwards. The collision between VAR_NM and a physical column of the target table is only checked at read time, as the hook does not have the target library assigned.
The simple rules are also configured as validation rules on the table itself, so they show up in the grid before submission: VAR_TYPE is a dropdown of C and N, VAR_LEN carries minimum and maximum values, and VAR_NM, VAR_DEPS, VAR_FMT and VAR_LOGIC are pattern checked. Validation rules are evaluated in the browser, so the post edit hook remains the authoritative check.
Derived values can expose hidden data
An expression can reference a column that is hidden from the user by Column Level Security, and the derived column will show the result. Configure derived variables with the same care as any other data exposure.
Performance
The expression is evaluated for each row read, before the filter. The filter already requires a scan of the table, so this adds per-row arithmetic rather than a second pass - but keep expressions cheap (no lookups, no subqueries), and expect the cost to be paid on every load of the EDIT screen, including each request for filter values.